Agents
An AI agent’s shell dies when its turn ends, so anything it starts dies with
it. That is the same problem lazycomd solves for you, applied to something
that cannot press q: the agent starts your API, runs the tests, reads the
crash log, and the process is still up on its next turn.
Two ways in — the CLI with --json, or MCP.
MCP
claude mcp add lazycomd -- lazycomd mcp
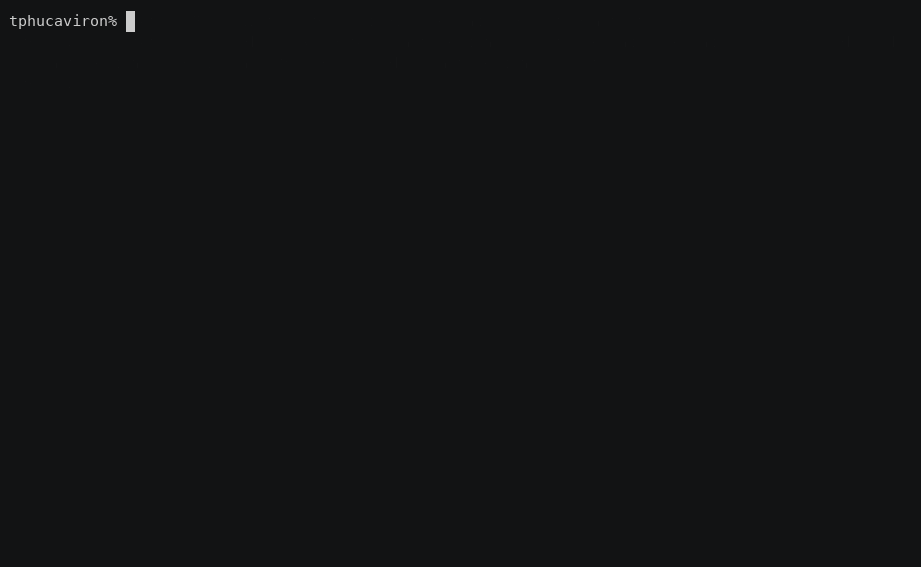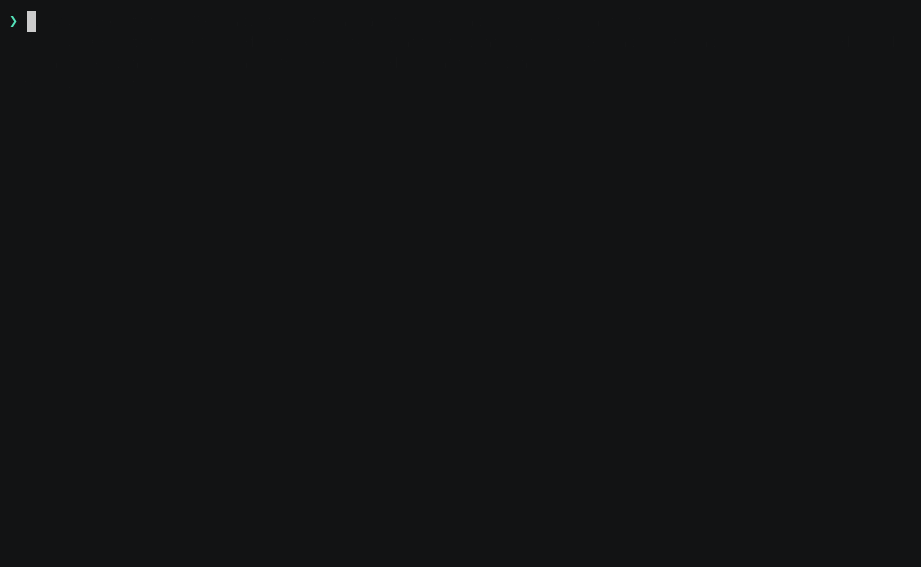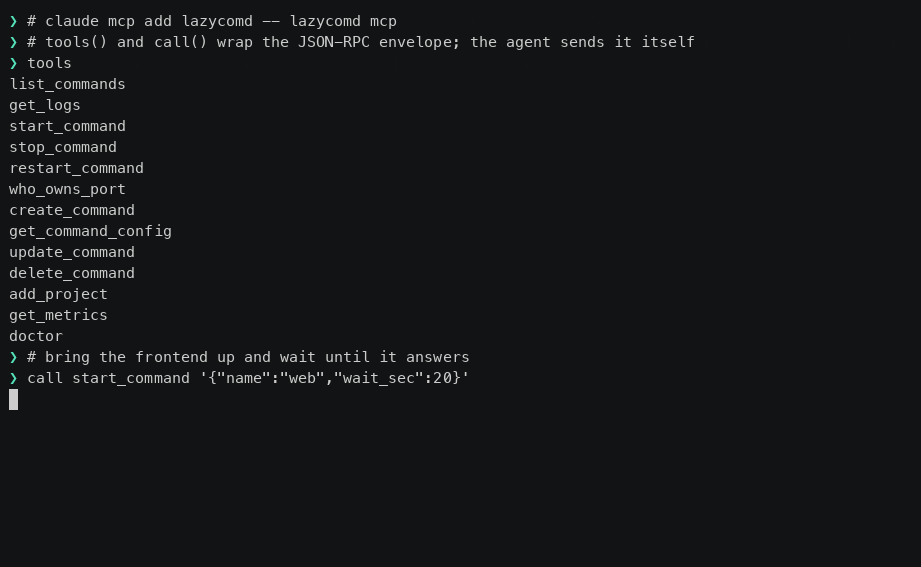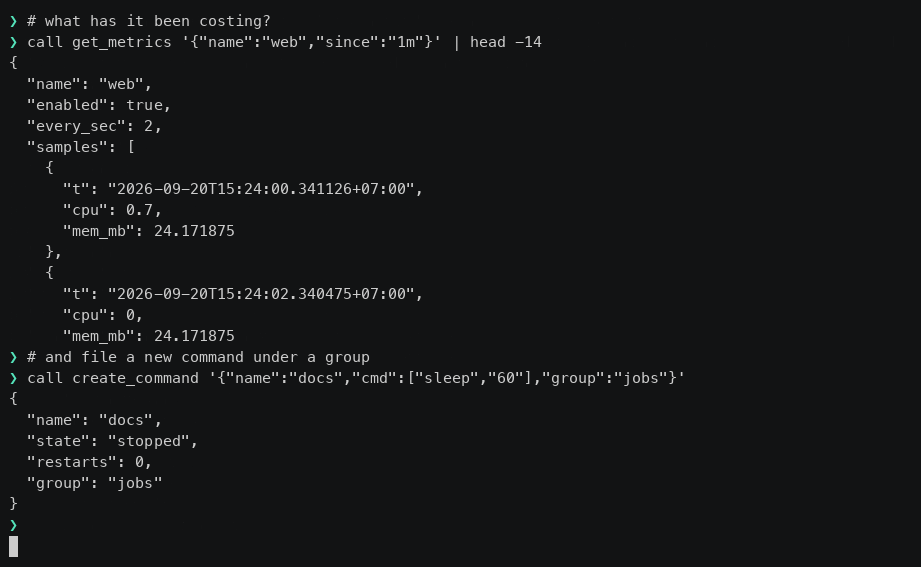
That is the whole setup. The server speaks line-delimited JSON-RPC on stdio and talks to the same daemon the TUI does, so what the agent starts shows up in your TUI and survives its session.
| Tool | What it is for |
|---|---|
list_commands |
What exists, what is running, restart counts, health |
get_logs |
The tail of one command’s output, after a failure |
start_command |
Start; wait_sec blocks until ready, so the next step can assume it is up |
stop_command |
Stop one command |
restart_command |
Restart, for example after changing a config it reads at boot |
who_owns_port |
Which process holds a port, and whether it is one of ours |
add_project |
Read a directory’s lazycomd.yaml too, so commands can live with the code |
get_metrics |
cpu and memory over time — whether memory is climbing or a spike settled |
doctor |
What will fail to start, before spending an hour on something that cannot run |
create_command |
Register a new command in the config file, group and all |
get_command_config |
One command’s full spec — read this before updating it |
update_command |
Replace a command’s spec |
delete_command |
Remove a command from the config for good |
The read-only tools — list_commands, get_logs, who_owns_port,
doctor, get_command_config, get_metrics — are safe to auto-approve. The rest change
processes or your config file; leave those prompting.
update_command replaces the whole spec, so an agent should read
get_command_config first and send back what it is not changing. A spec the
daemon rejects is never written: the config it refuses is the config it can no
longer load.
What an agent does with it
Verify a change end to end. Edit the code, start_command with
wait_sec: 30, run the test suite, get_logs on failure. The stack is still
running for the next question instead of being rebuilt every turn.
Explain a blank page. list_commands shows web failed with three
restarts; get_logs shows the missing module. No copy-pasting stack traces.
Settle a port fight. “Port 3000 is in use” becomes who_owns_port 3000:
held by datagrip, pid 15921, not a lazycomd command. Now it can tell you who
to kill rather than guessing.
Pre-flight a long task. doctor first. A depends_on pointing at a
command that was renamed is a five-second fix before the work, and a confusing
half-hour after it.
Register what it scaffolded. A new service gets create_command with its
cwd, port, health and depends_on, so the work outlives the conversation and
starts with everything else tomorrow.
Catch a crash loop it caused. Between edits, list_commands and watch
restarts climb — found while the change that caused it is still on screen.
Without MCP
Every verb has --json, so an agent with a terminal needs nothing else:
lazycomd doctor --json                 # anything broken before we start?
lazycomd start api --wait 30s      # up, or a non-zero exit
lazycomd ls --json                     # what is running now
lazycomd logs api -n 50 --json     # why it is not
lazycomd port 3000 --json              # who has the port
start --wait exits non-zero if the command never becomes ready, so a shell
&& chain is enough control flow for most of it.
The protocol, briefly
lazycomd mcp implements initialize, tools/list, tools/call and ping
over stdio. A tool failure comes back as isError content rather than a
JSON-RPC error — an unknown command name is something to read and act on, not
a broken session. Try it by hand:
echo '{"jsonrpc":"2.0","id":1,"method":"tools/list"}' | lazycomd mcp